ERP/CRM reconciliation pipeline
Generate realistic, deliberately messy synthetic ERP and CRM exports, and reconcile them back into a single source of truth.
Get started Explore the architecture
What the repository demonstrates
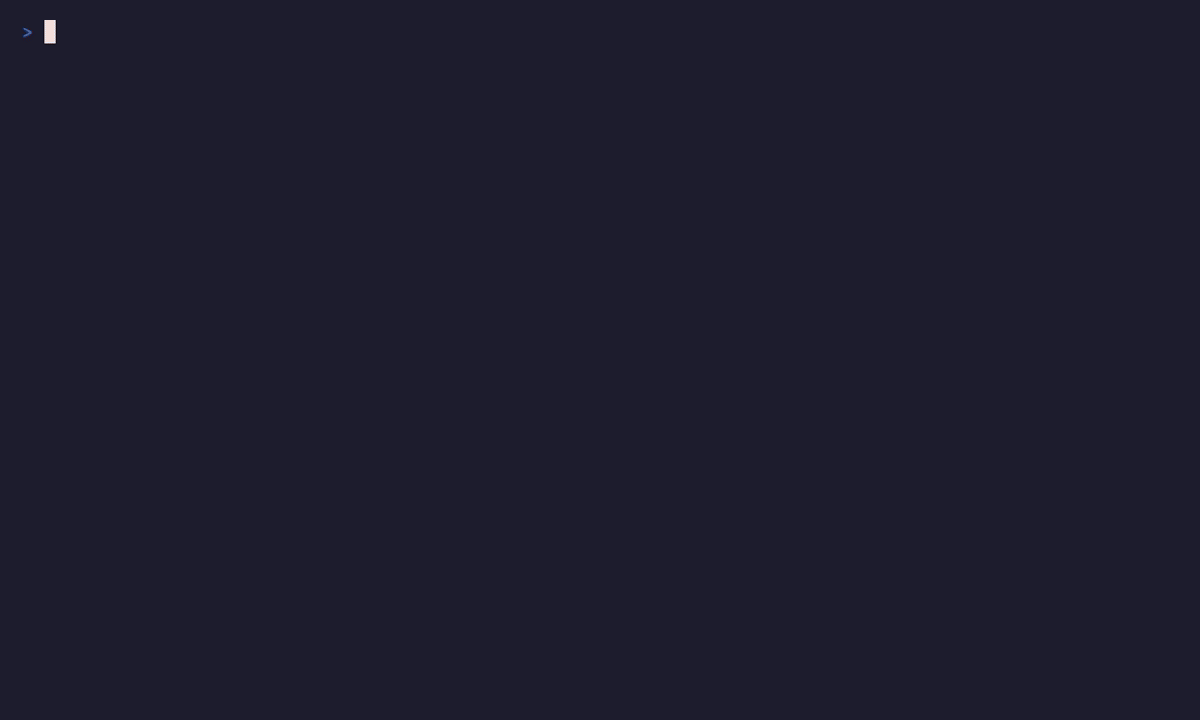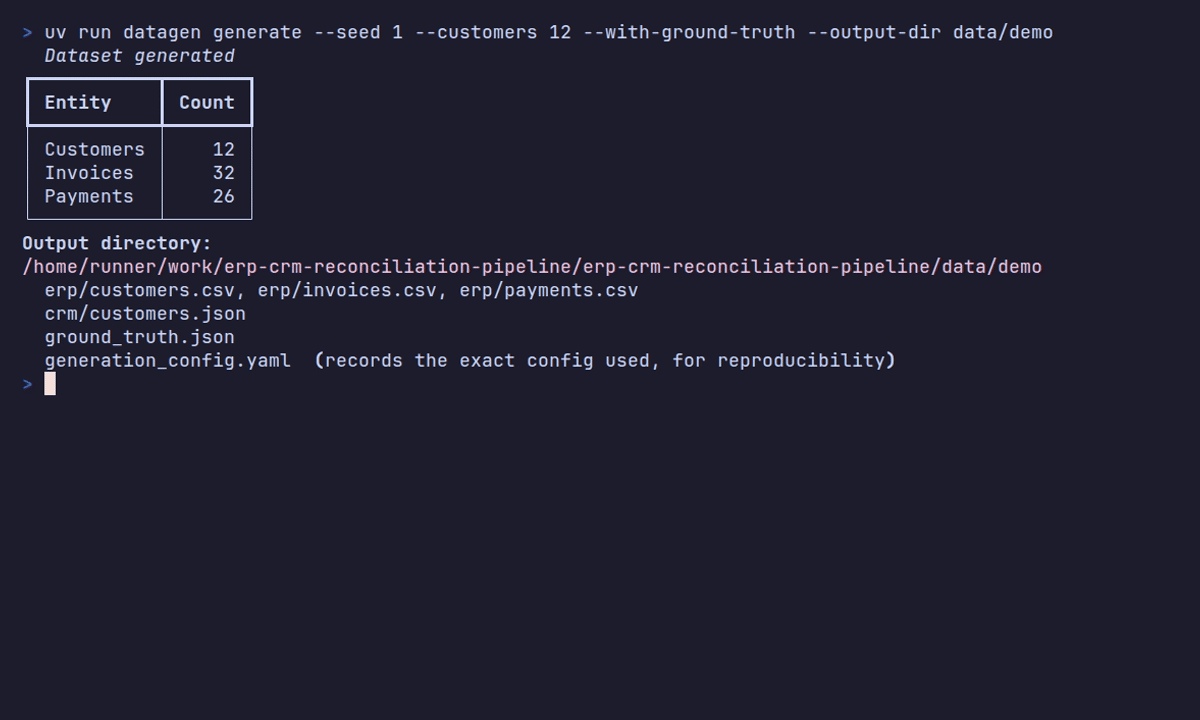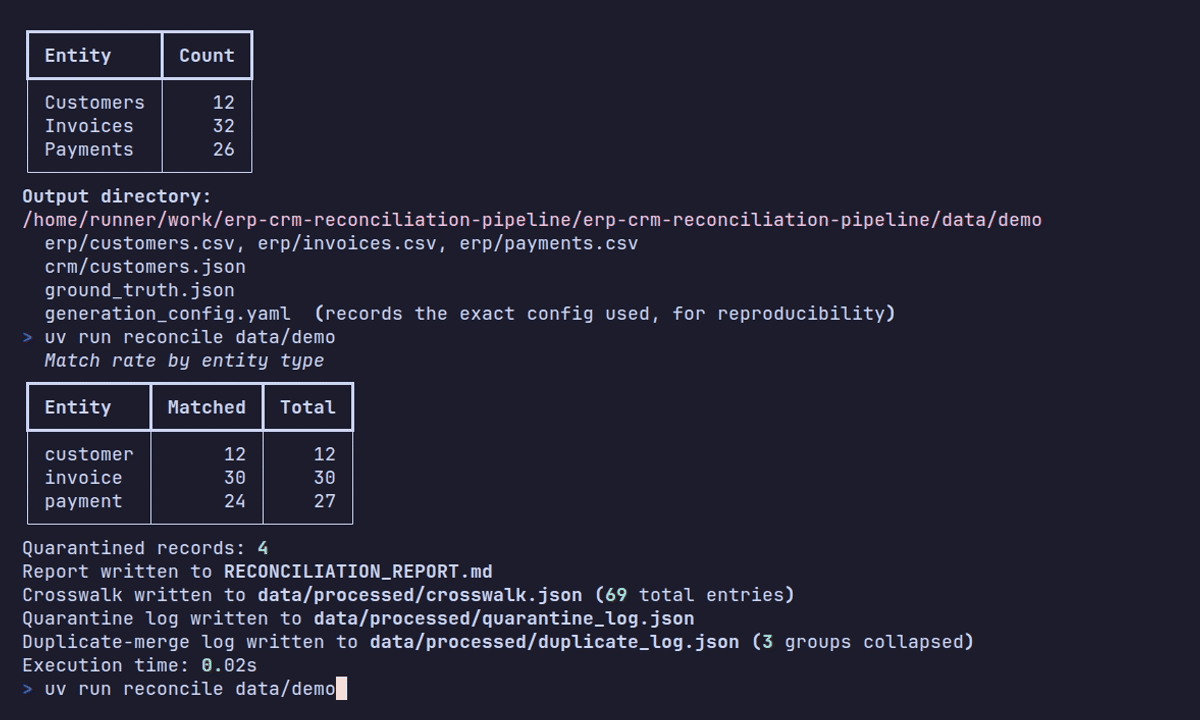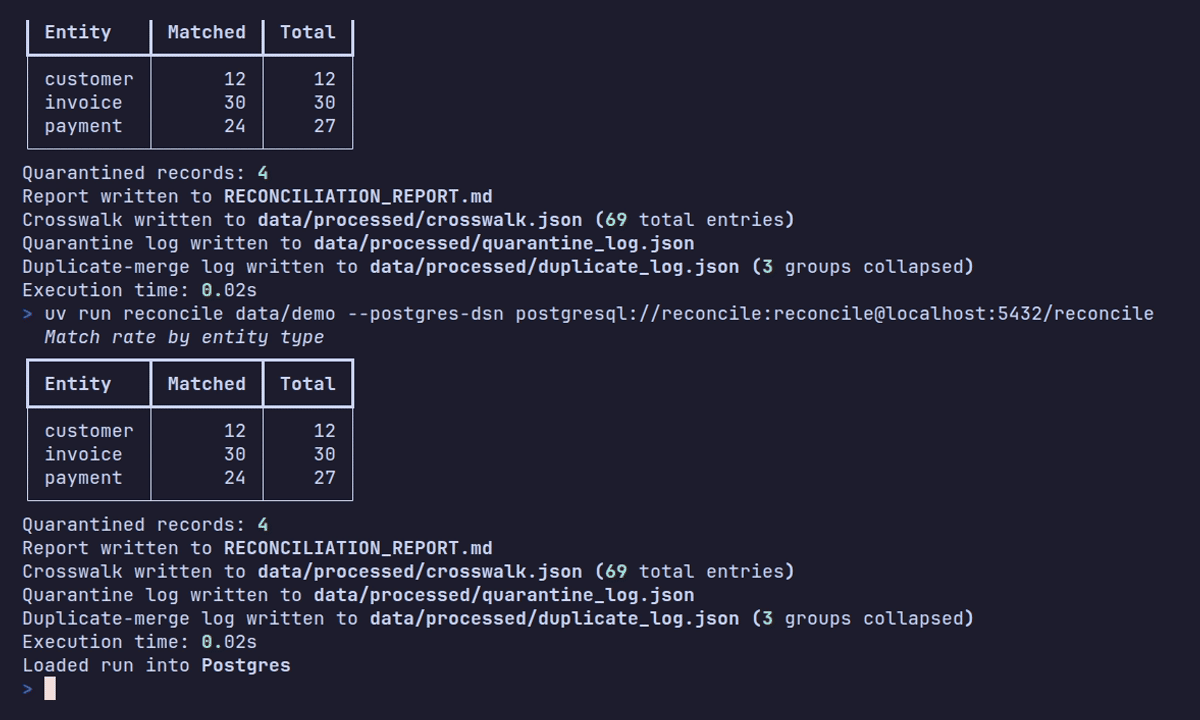
- Synthetic customer/invoice/payment generation with Faker and mimesis, fully reproducible from a single seed.
- Two deliberately divergent exports of the same underlying data: an ERP-style flat CSV using legacy field names, and a CRM-style nested JSON using camelCase field names -- mirroring how a real SAP/Salesforce-style hybrid legacy stack disagrees with itself.
- Composable "messy data" injection: inconsistent/invalid date formats, mixed-encoding corruption, missing values, and near-duplicate rows, applied independently per export.
- Genuine cross-system discrepancies -- orphan records and legitimate ERP/CRM amount drift -- with an optional
ground_truth.jsonanswer key for scoring a downstream reconciliation pipeline's precision/recall. - A reconciliation pipeline (
Polars+Pydantic) that ingests both exports, cleans and validates every row, resolves ERP records against CRM records by name/email/phone/date/amount proximity (never by business-key format), and produces a crosswalk plus a Markdown reconciliation report. - A Typer CLI for both stages (
datagen generateandreconcile),pydantic-validated configuration and data models, and a fully typed (mypy --strict) codebase with high test coverage. - A written specification,
CLAUDE.md, that pins down the pipeline's business rules (the four resolution outcomes, tolerance thresholds derived from the generator, "ask rather than guess" on ambiguity) before any pipeline code existed -- and caught a real contradiction in an early documentation draft.
Choose a path
| Goal | Start here |
|---|---|
| Generate a dataset and inspect the CLI | Get started |
| Run the reconciliation pipeline over a generated dataset | Get started |
| Understand how the pieces fit together | Architecture |
| Look up CLI flags or the data schema | Reference |
| Inspect the implementation | Repository on GitHub |
Two steps, one pipeline
This project has two parts, run in order. Step one, datagen, generates
the messy ERP/CRM exports (and optionally ground_truth.json). Step
two, reconcile, ingests those exports, cleans and validates them,
resolves ERP records against CRM records, and writes a crosswalk and
reconciliation report. See Architecture for how the
two fit together.